AI for CIOs
How Should a CIO Compare AI Risk Evidence Across Business Units?
SimplSolutions Editorial Team · 7 min read
Published
The CIO’s problem is not identical use cases. It is unequal evidence.
Two business units may ask to expand assistants that appear nearly identical: both answer questions from internal documents, both have employees as users, and both promise faster access to knowledge.
That surface similarity can make approval feel simple. It is not. One assistant may be limited to a reviewed policy library with clear ownership. The other may draw from mixed repositories, expose information across teams, or have unresolved examples of confident but unsupported answers.
A useful CIO decision therefore asks more than, “What is the risk score?” It asks, “What do we know, how do we know it, and what remains unproven?”
NIST’s AI Risk Management Framework offers voluntary guidance intended to help organizations manage risks to individuals, organizations, and society and incorporate trustworthiness considerations into AI design, development, use, and evaluation. It is useful context—not a universal approval checklist or a claim that a system is safe because it references NIST.
Compare purpose and source evidence
For each proposed assistant, create a short decision record with the same fields. The point is consistency without pretending that every use case has the same consequences.
Business purpose and consequence of error
Start with the task, not the model.
Document what the assistant is expected to help with, who relies on it, and what happens when it is wrong. An assistant that helps an employee find a benefits policy is not equivalent to one that summarizes information used in a customer commitment, operational decision, or regulated process.
Ask:
- What decision or activity does the assistant support?
- Is the output informational, advisory, or used to trigger action?
- Who could be affected by an incorrect or incomplete answer?
- What is the acceptable response when the system cannot support an answer?
This category often explains why two technically similar assistants deserve different controls.
Approved sources and source ownership
Record which repositories the assistant may use, who owns them, and how the business determines that they are appropriate.
A department should be able to distinguish between an approved source and a merely connected source. A document being accessible to an integration does not make it authoritative for every question.
For a multi-business-unit knowledge assistant, compare:
- Whether source inclusion has a named business owner
- Whether outdated, duplicated, or conflicting material is identified
- Whether sensitive collections are intentionally excluded or separately governed
- Whether an answer can show which approved material supports it
- What happens when approved sources disagree
The evidence standard should rise with the consequence of the answer. “The assistant searched a repository” is not the same as “the answer was grounded in an approved source that the responsible team maintains.”
Evaluate access boundaries and failure evidence
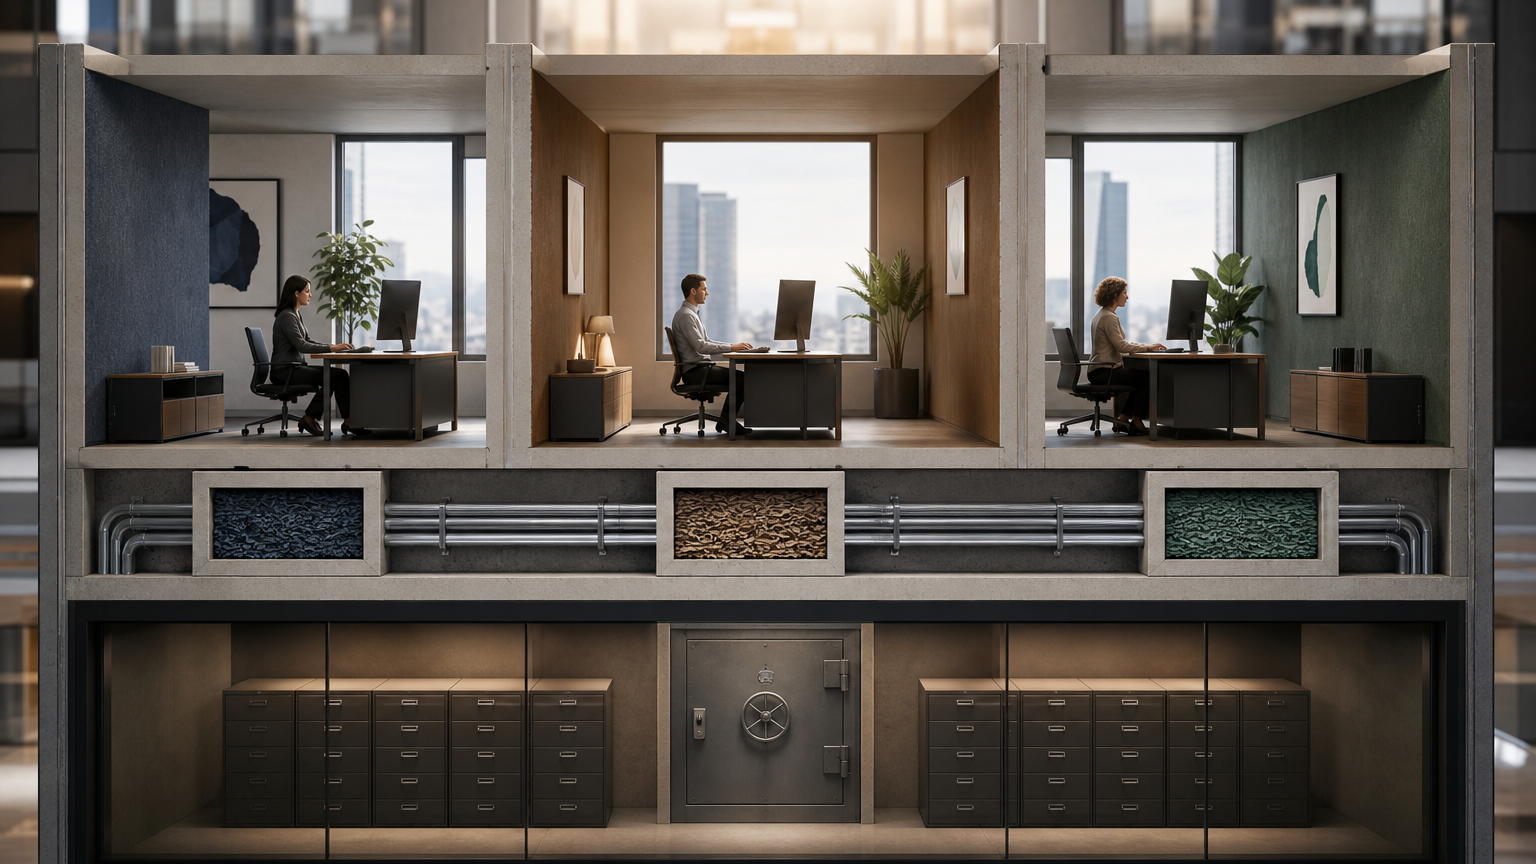
Access scope and boundary evidence
Do not record access as a binary feature. Record whose information the assistant can retrieve, under what identity, and for which business purpose.
Compare the proposed user population, connected systems, data categories, and separation between business units. Pay particular attention to whether a user could receive information simply because the assistant can reach it, rather than because that user is authorized to receive it in context.
Evidence may include a documented access scope, representative denial tests, and review of exceptions. The decision record should state what was tested and what was not tested. A claimed boundary without test evidence is an assumption, not a control conclusion.
Failure evidence, not only success examples
Demonstrations usually show the assistant working. Approval decisions need evidence about when it does not.
Ask each business unit to provide representative failure cases, such as:
- An answer unsupported by the approved sources
- A confident answer where the correct behavior was to abstain
- A response that combined information across an inappropriate boundary
- A failure to reflect a current policy or document version
- A prompt or request that produced an answer outside the intended task
The comparison should consider both the severity of failures and the quality of the organization’s response. A team with more documented failures may actually have stronger governance if it found them through deliberate evaluation and resolved them transparently.
Assign operating responsibility and assess exceptions
Human review and operating responsibility
“Human in the loop” is too vague to be useful on its own. Record who reviews what, at which point, and with what authority.
For example, a reviewer might verify an answer before it is used in an external communication, while an employee-facing lookup may require users to confirm the source themselves. Those are different operating models and should not be summarized by the same checkbox.
The decision record should identify:
- The person or role accountable for the use case
- The outputs that require review
- The evidence a reviewer is expected to examine
- The action to take when the answer is incomplete or disputed
- How incidents and recurring errors are reported
Human review is not a substitute for clear scope. It can reduce exposure in some workflows, but it can also become a ritual if reviewers cannot see the basis for an answer or are not empowered to reject it.
Unresolved exceptions and evidence quality
Every proposal should list what remains uncertain. This is where a CIO can distinguish a manageable gap from a reason to delay.
Examples include an unverified source owner, an incomplete access test, a known failure without a compensating control, or a dependency on a process that has not yet been assigned to an accountable team.
Compare exceptions by consequence, not by count. Five low-impact documentation gaps may be less important than one unresolved cross-business-unit access question.
Also record evidence quality:
- Is the evidence current?
- Is it specific to this use case?
- Was it independently reviewed or self-reported by the proposing team?
- Does it cover normal use and misuse?
- Can another reviewer reproduce the conclusion from the record?
A worked comparison: two knowledge assistants
Imagine Finance and Operations each request broader access to a knowledge assistant.
Finance proposes an assistant limited to an owned policy collection. Its record identifies the business owner, lists the intended users, shows examples of unsupported questions, and requires a human check before information is used in a formal reporting process. One open issue remains: a legacy folder has not yet been reviewed.
Operations proposes a similar assistant connected to several team repositories. Its record describes the expected productivity benefit but does not clearly identify source owners. Testing shows useful answers, but the team has not documented how the assistant handles conflicting procedures or requests from users outside the operating group.
A generic risk score could obscure the distinction. A better decision might be to approve Finance for a bounded expansion, delay Operations until source ownership and access boundaries are evidenced, and require both teams to maintain failure records and review procedures.
That is not inconsistent treatment. It is consistent evidence applied to different conditions.
Turn the comparison into a decision
A CIO can use four decision outcomes rather than forcing every proposal into approve or reject:
- Approve within the documented scope. The purpose, sources, access boundaries, failure behavior, and human responsibilities are sufficiently evidenced for the proposed use.
- Approve with conditions. The use may proceed only with explicit limits, such as a narrower source set, smaller user group, additional review, or a time-bound reassessment.
- Delay pending evidence. A material uncertainty—especially around access, source authority, or consequential use—prevents a responsible decision.
- Decline the proposed expansion. The intended use does not have an acceptable control path, or the residual uncertainty is disproportionate to the expected value.
The decision should name the evidence that would change the outcome. “Improve governance” is not an actionable condition. “Document ownership for the connected collections and complete representative denial testing for cross-unit requests” is more useful, without prescribing a particular implementation.
What this method does not solve
A decision record does not eliminate judgment. It does not prove that an assistant will behave correctly in every future interaction, and it does not replace privacy, security, legal, records, or sector-specific review where those obligations apply.
NIST describes its AI Risk Management Framework as voluntary. Organizations should therefore treat it as a structure for thinking and comparison, not as a certification, regulatory safe harbor, or substitute for internal accountability.
The record also needs maintenance. Sources change, user populations expand, and a low-consequence lookup can become embedded in a higher-consequence workflow. Approval should describe its scope and reassessment trigger rather than becoming permanent by default.
A practical next step for the CIO office
Ask every business unit seeking AI expansion to submit the same one-page decision record: purpose, approved sources, access scope, failure evidence, human review, and unresolved exceptions.
Then compare the completeness and strength of the evidence before comparing the promised productivity outcome. This creates a common language for prioritization while preserving room for different controls by use case.
The goal is not to make every assistant look equally safe. It is to make the basis for each decision visible, testable, and accountable.